NEWS → · Models · Cloudflare
Cloudflare open-weights Clairic: 27B and 9B extraction models under Apache 2.0
Nov 19, 2026
Cloudflare released the full weights of Clairic and the new Clairic-flash on Nov 18, 2026, under Apache 2.0 — two purpose-built extraction models that turn text, images and PDFs into typed values, estimates and forecasts, rather than chat replies. Clairic is a 27B model built on Qwen3.8-27B; Clairic-flash is a 9B model built on Qwen3.5-9B. Both also run hosted on Workers AI at $0.24 and $0.10 per million input tokens respectively, with no charge for output tokens — and both are $0.10 until Dec 1, 2026. The picture is Cloudflare's own extraction comparison from its announcement.
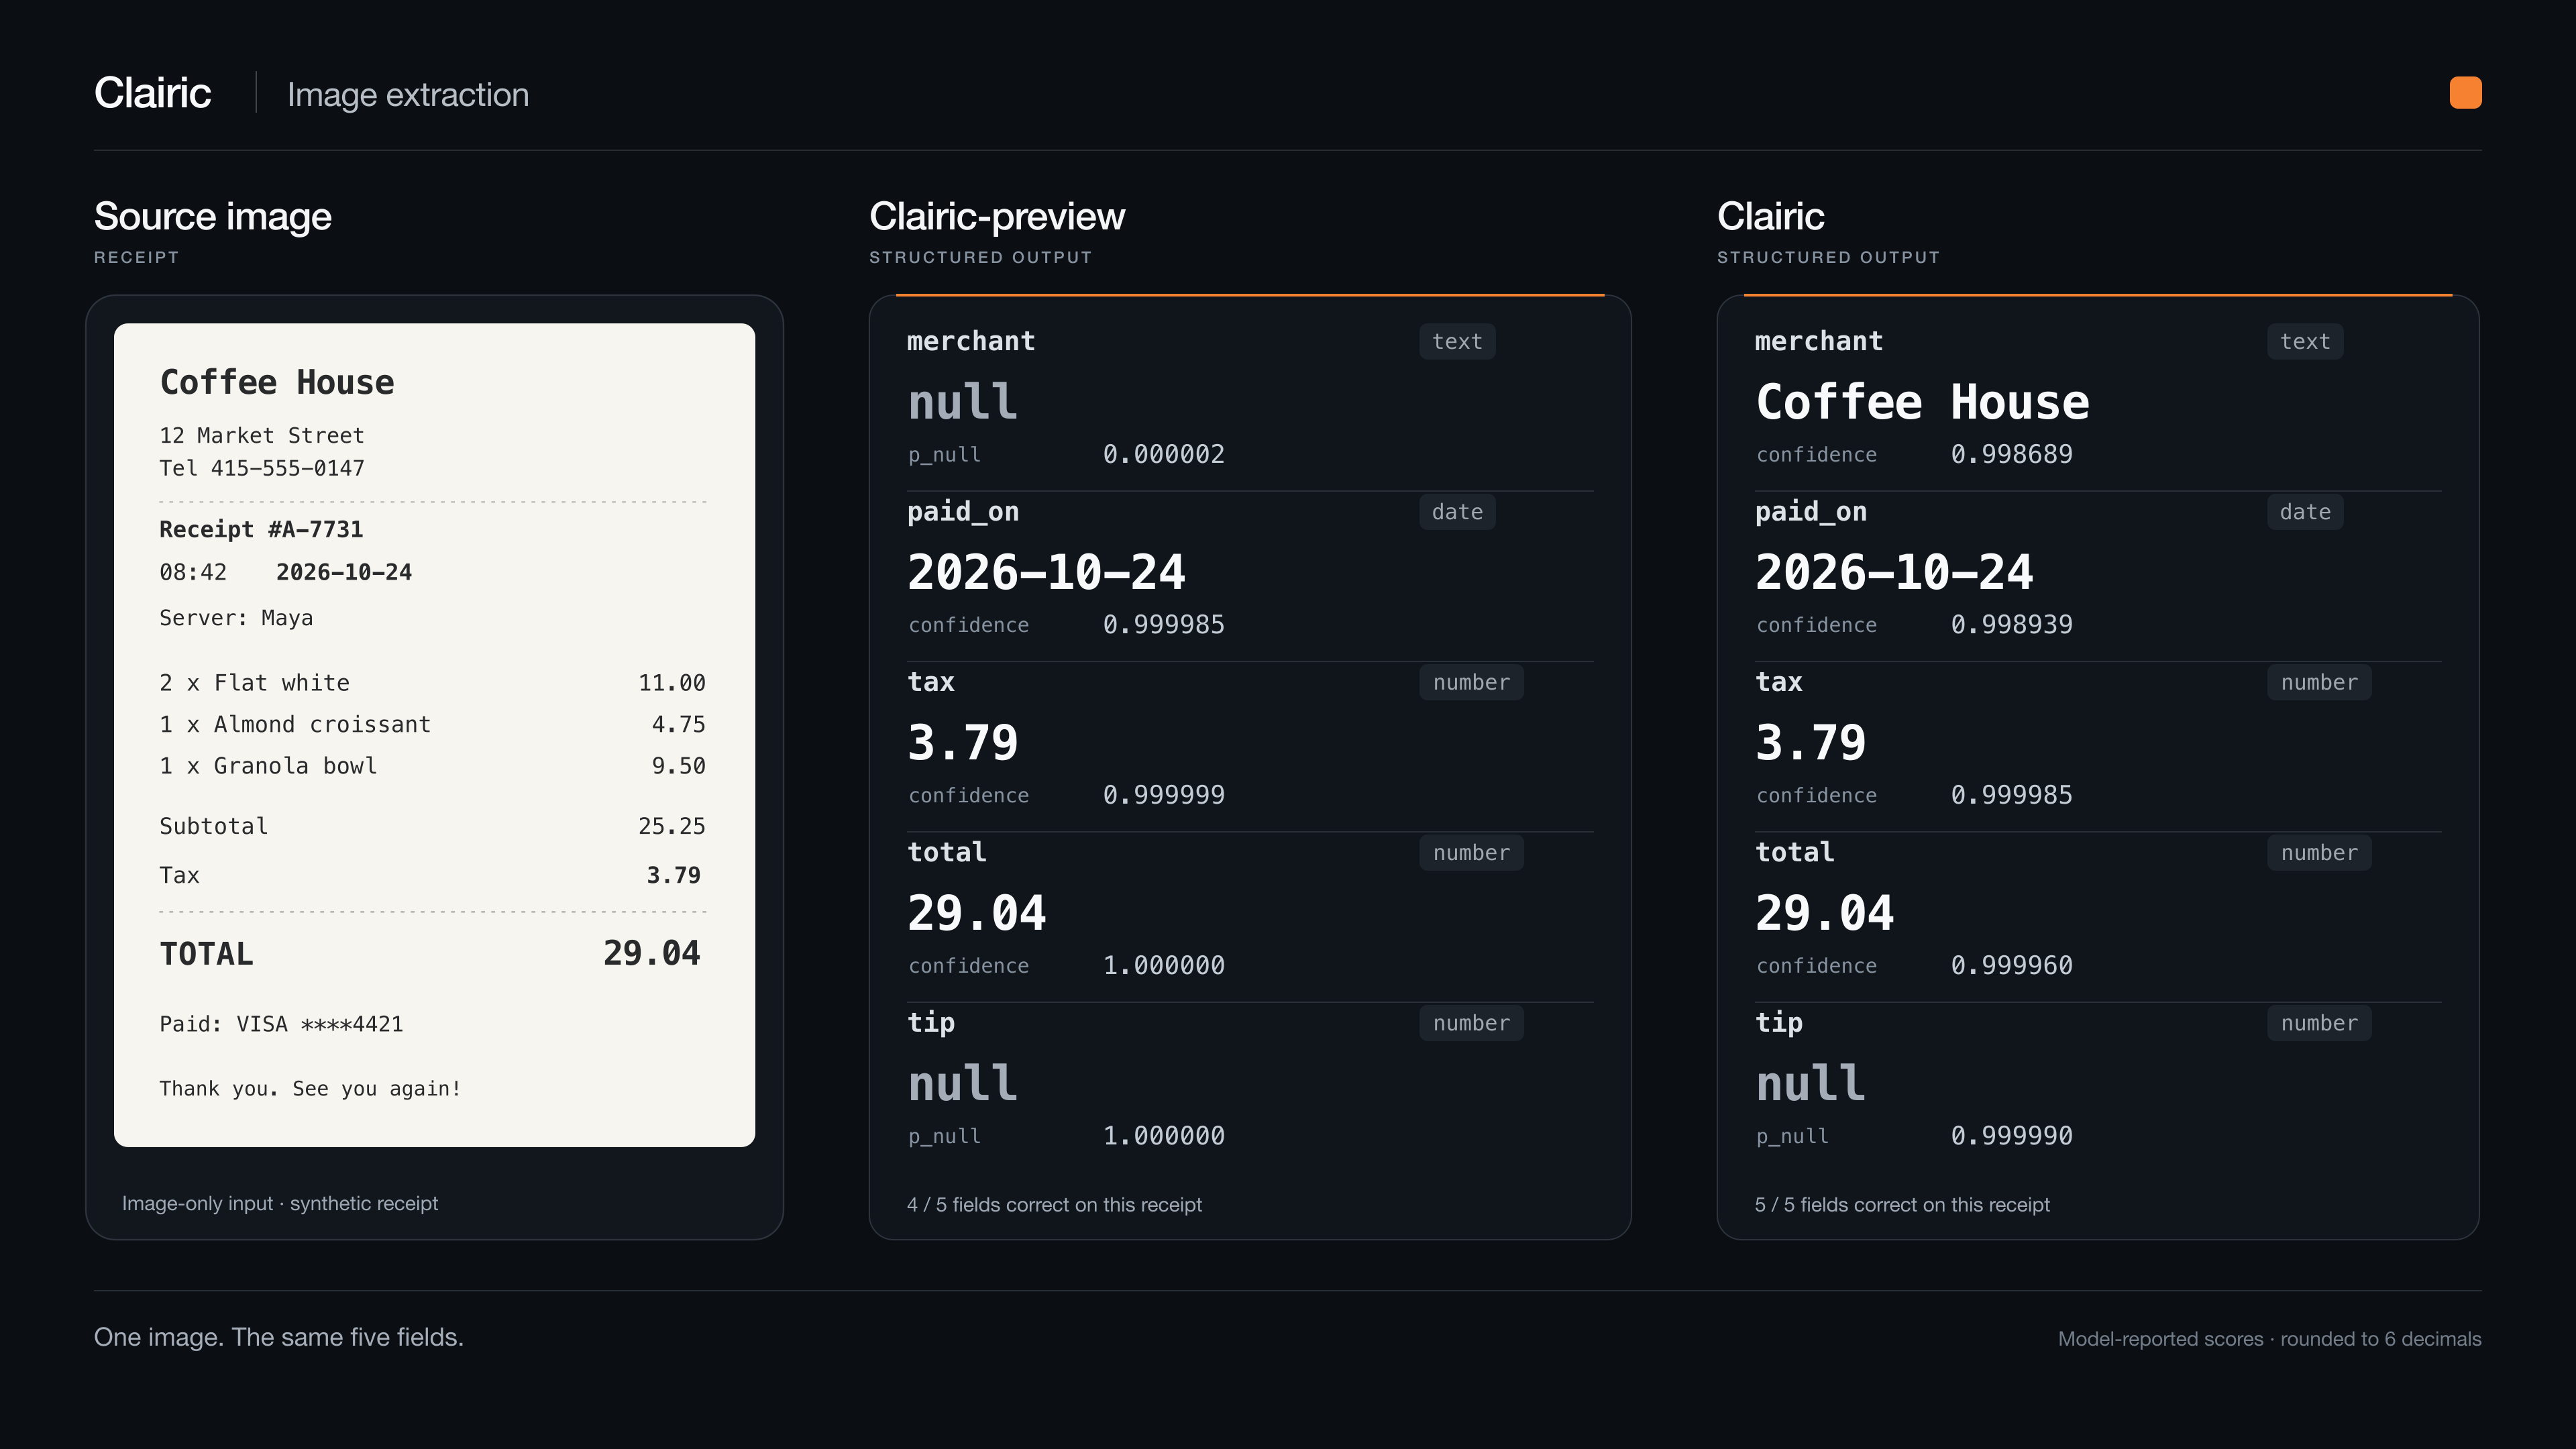
Image: Cloudflare via blog.cloudflare.com
What the release contains, from Cloudflare's announcement and the models' own cards: a typed-output head alongside the weights, per-field confidence and null-probability scores, and special heads for estimates, forecasts and arithmetic. Clairic reads up to four images or PDF pages per request. Cloudflare is plain that the evidence is its own: it states there are no public extraction benchmarks yet, and its headline figures are internal — on its fresh-text test set Clairic extracted 335 of 336 fields correctly and Clairic-flash 328, against 295 for the hosted preview these models replace; on synthetic receipts both scored 576 of 576. Treat those as the maker's measurements, not independent results.
The hosted price is the comparator a self-hoster has to beat: input tokens only, at $0.10 per million for Clairic-flash and $0.24 for Clairic after the Dec 1 promotion ends. The models are now in our catalogue, labelled as specialised extraction models — their fit maths describes an extraction workload, not a general chat deployment.
What it means if you rent GPUs
For renters this is a different shape of job from the chat models that fill most of the catalogue: document pipelines — invoices, receipts, forms — where the rental unit is one modest GPU, not a cluster. By memory arithmetic the 27B model at full precision is about 54GB, one H100, L40S or A100 80GB class card; the 9B flash model is about 18GB, one consumer 24GB card. Whether self-hosting beats the hosted per-token price depends on volume, which is exactly the break-even question the catalogue entry now frames.