NEWS → · Models · OVHcloud
OVHcloud's Olala mini weights are live: a 6.8B MoE with 1B active, Apache 2.0 — that only OVHcloud's forks can run today
Nov 19, 2026
OVHcloud published the weights of Olala v1.0 mini 7A1B today, Nov 19, 2026, launching the model formally at its AI Summit in Paris. The model card — read first-hand by this desk — corrects the launch material in one place: the model totals 6.8 billion parameters, not 7 billion, with about 1 billion active per token, across 36 layers of which only seven are attention layers and the other 29 are Mamba-3 state-space layers, each followed by a mixture-of-experts block with 256 routed experts of which six fire. The context window is 32,000 tokens, the licence is plain Apache 2.0 with no revenue or user-count trigger, and the picture is OVHcloud's own diagram of the architecture from the model card.
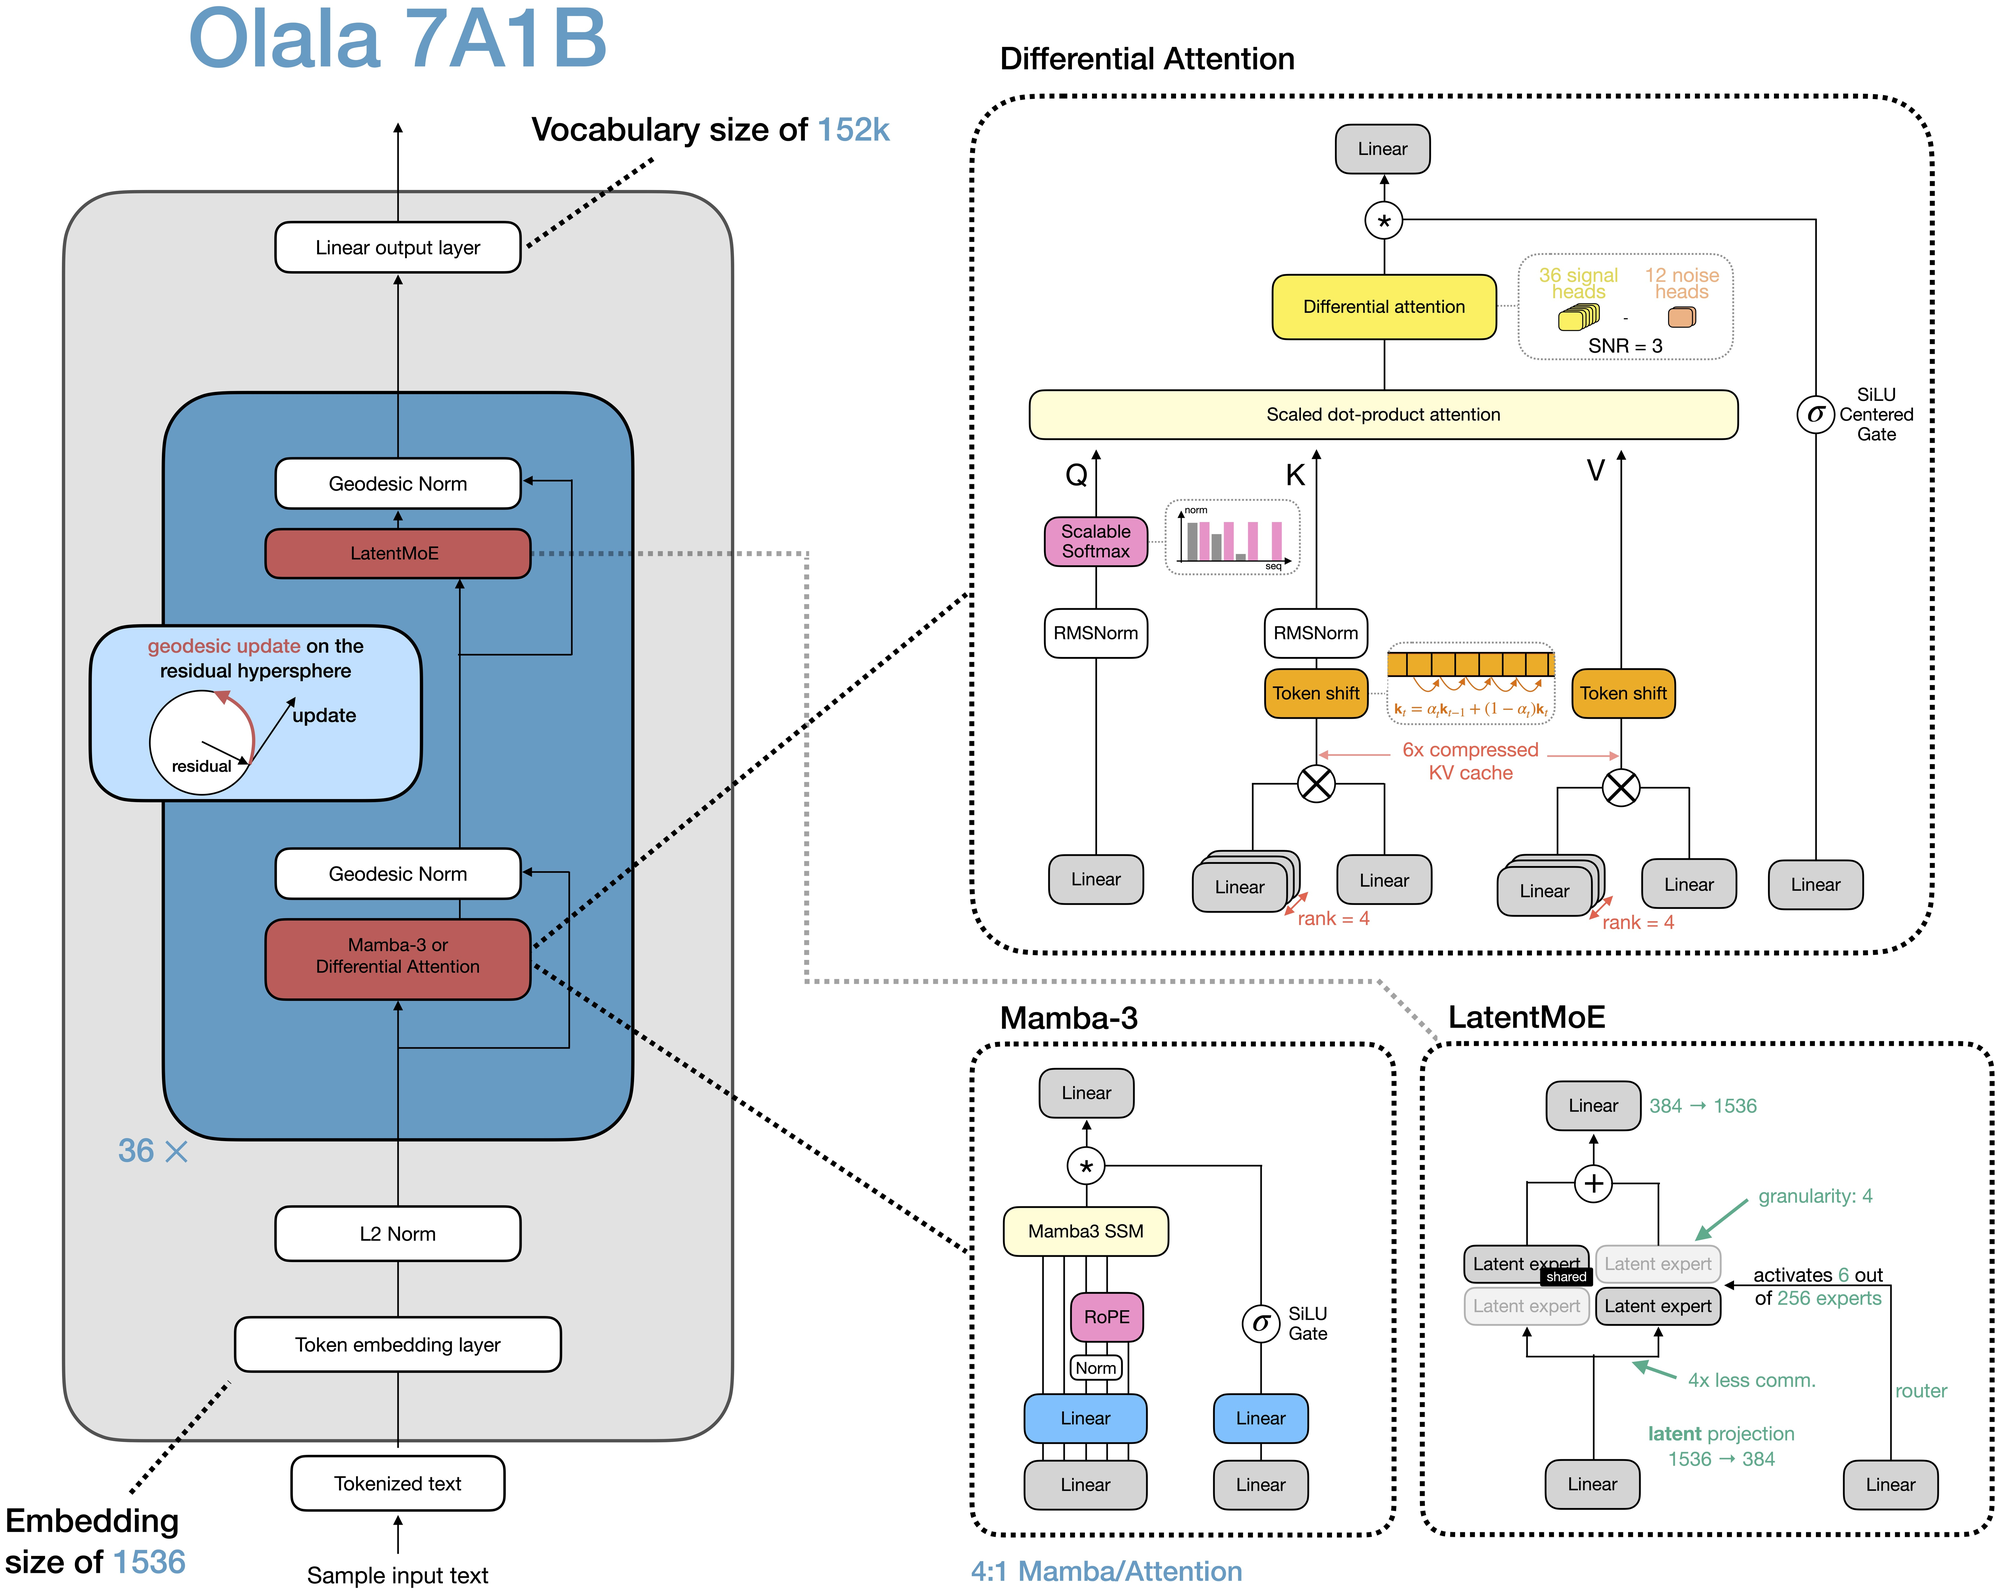
Image: OVHcloud / OVHai LLM via huggingface.co
What is in the repositories, from the card itself: the final post-trained model, a pre-trained base, an SFT build, and summarise and translate variants, plus GGUF and MLX routes. OVHcloud says the model was trained on 12.8 trillion tokens on the JUPITER, Jean Zay and MeluXina supercomputers, pre-trained in English and 36 other languages, and is already in production at the search engine Qwant for flash answers. The honest watch-out is the serving stack: upstream vLLM, llama.cpp, Ollama and LM Studio cannot load the new olala architecture yet — self-hosting today means OVHcloud's own forks (a vLLM fork or its pre-built Docker image, and its llama.cpp fork for the GGUF route). The card's vLLM route wants a 24GB or larger NVIDIA GPU and was tested on L4 and L40S cards; the GGUF route runs in 6 to 14GB. OVHcloud's own launch material says the model runs on a GPU with as little as 8GB — that is the maker's figure for the quantised route, attributed as such.
The same summit brought a second announcement, folded in here because OVHcloud's release for it carries no image of its own: a 55-product launch that adds NVIDIA B300 and Rubin R200 GPUs and the RTX PRO 6000 to OVHcloud's Bare Metal and Public Cloud lines. OVHcloud states its data-centre capacity could supply up to 60,000 B300 GPUs or 35,000 R200 GPUs — a company-stated capacity figure, not installed, priced inventory; no GPU prices were published in the release, and several of the 55 products are December previews rather than available today. This desk will treat OVHcloud as a board candidate when priced, bookable GPU rows appear.
What it means if you rent GPUs
For self-hosters this is the small end of the board done properly: an Apache 2.0 model with no licence trigger, sized so that one modest card holds it — about 13.6GB at full precision by memory arithmetic from the card's parameter count, and far less quantised — from a European provider whose pitch is sovereignty. The trade is maturity: the architecture is days old, the serving tools are the maker's forks rather than the upstream projects most teams already run, and every performance figure so far is OVHcloud's own. The model is now in our catalogue with its sizes worked from the card.