NEWS → · Models · Ricursive Intelligence
Ripple-65B Preview is out — a 65B Apache 2.0 coding model that runs on one GPU
Nov 5, 2026
Released on Nov 4, 2026 by Ricursive Intelligence — the lab founded by the researchers behind Google's AlphaChip — Ripple-65B Preview is a dense 65-billion-parameter model under a plain Apache 2.0 licence, with a self-reported agentic-coding score ahead of open models eight to fifteen times its size, and an NVFP4 checkpoint built to fit on a single GPU.
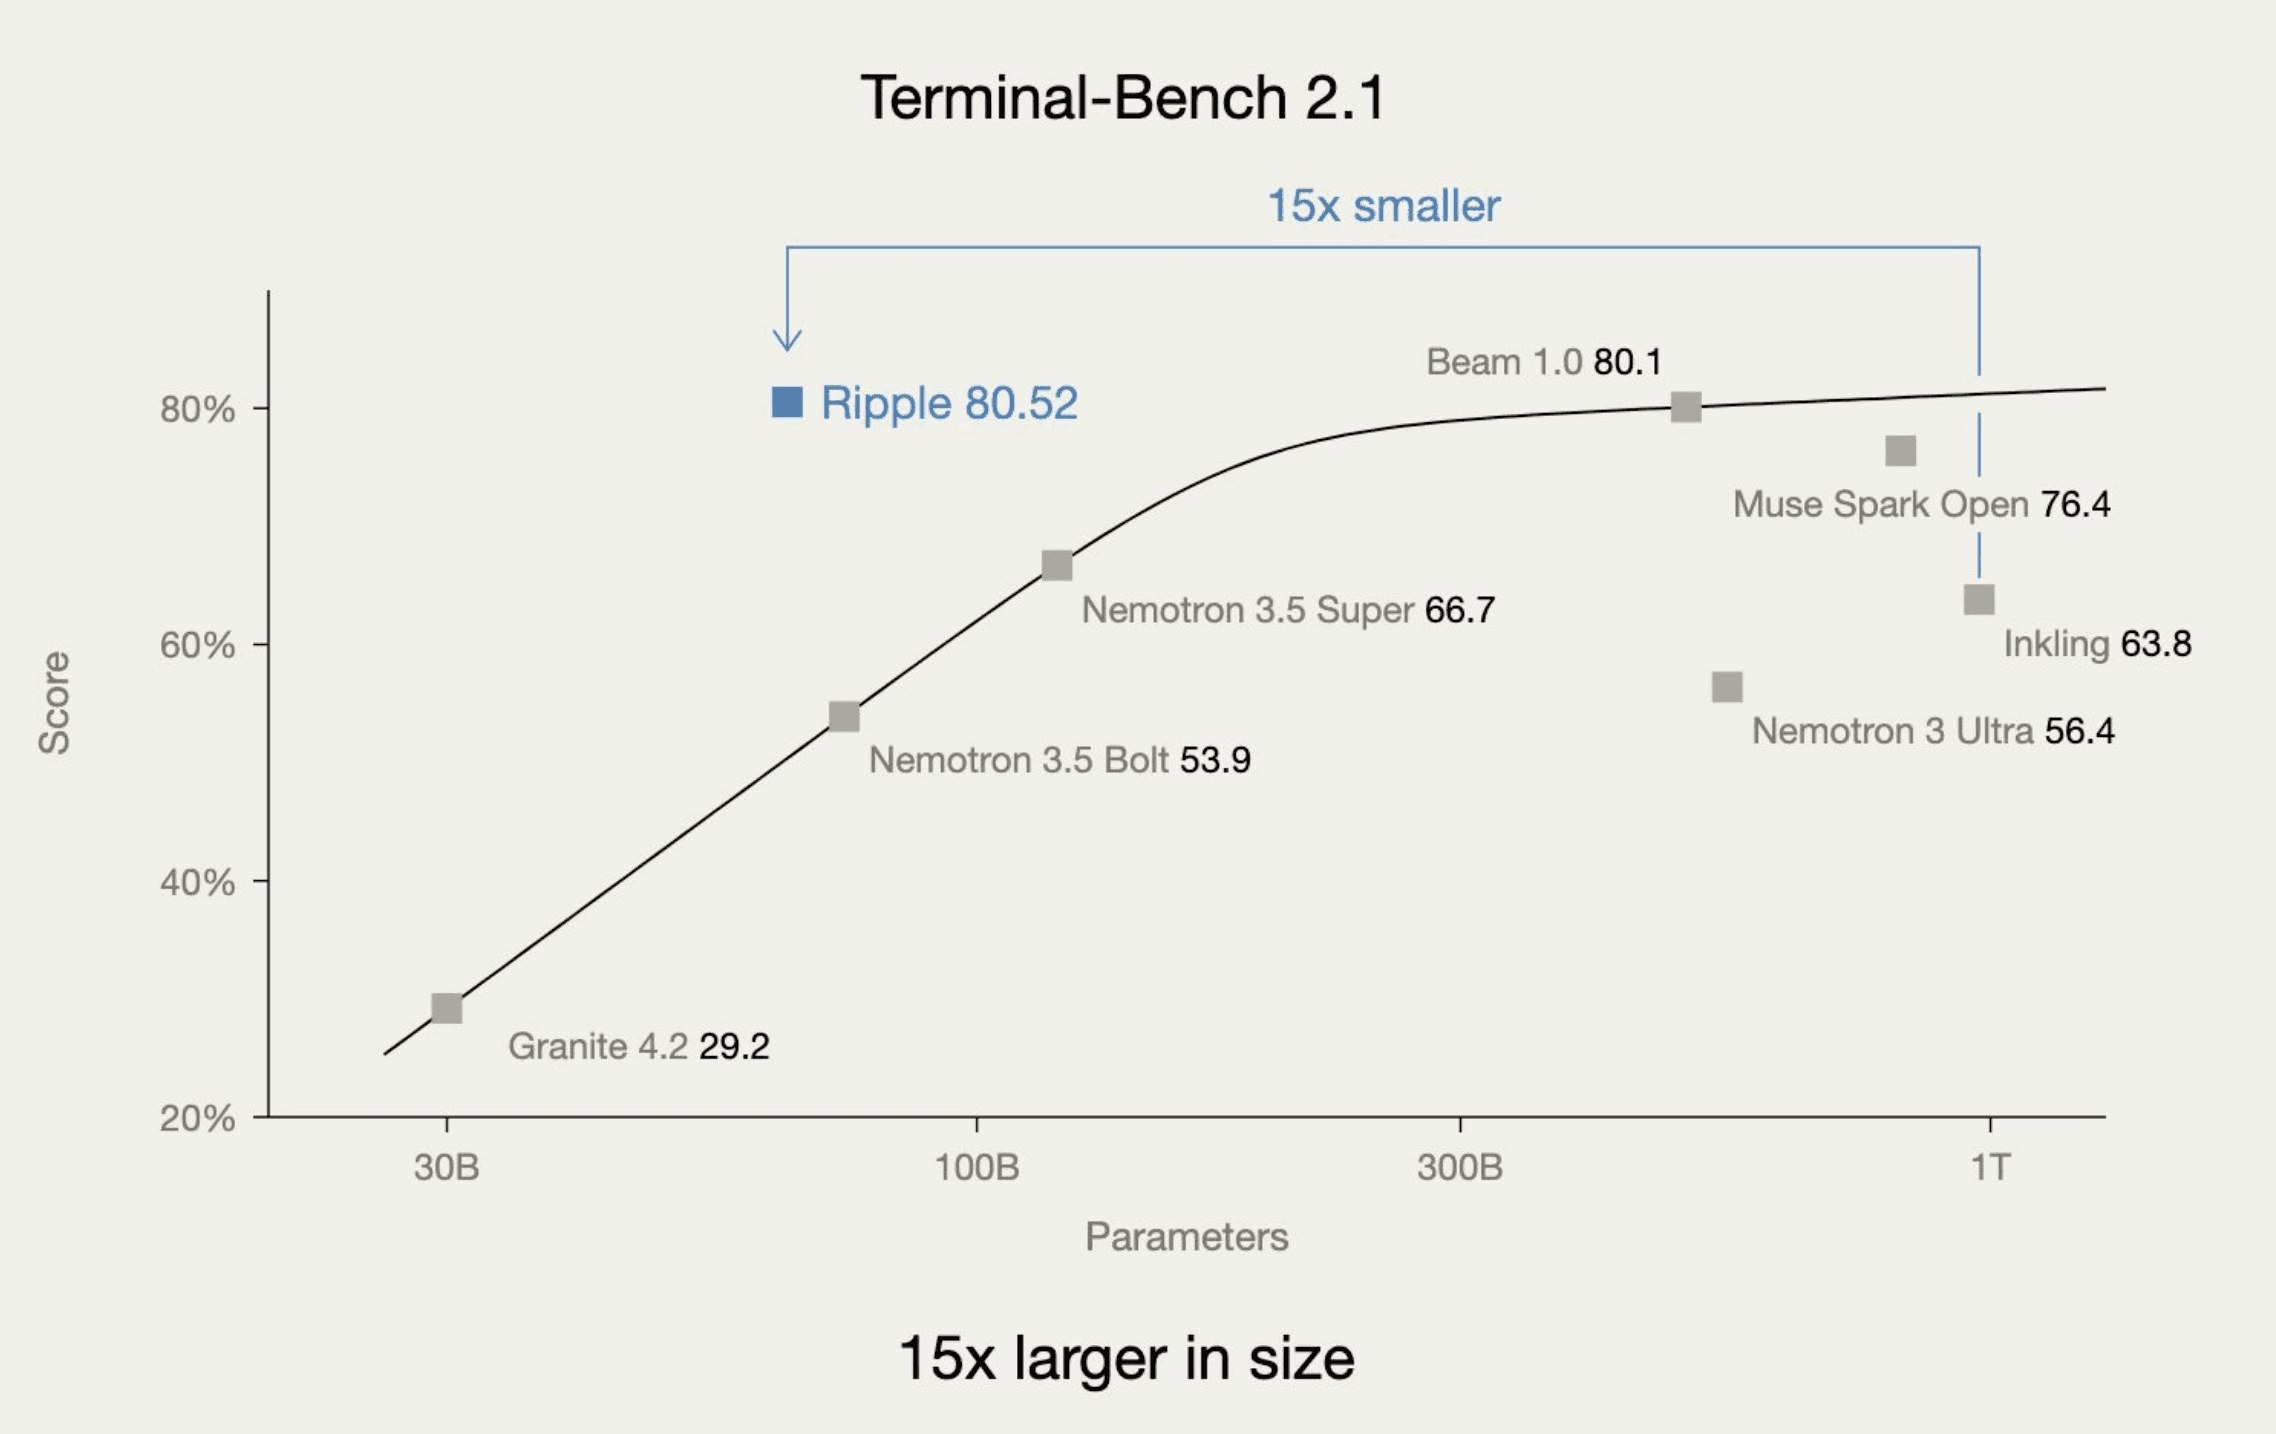
Image: Ricursive Intelligence via ricursive.com
What was released, from Ricursive's launch blog and the model's Hugging Face card, both read on Nov 5, 2026: a 65B-parameter dense Transformer (80 layers, all 65B active on every token — no mixture-of-experts shortcut), pretrained from scratch on 12 trillion tokens, with context up to 1 million tokens. Three checkpoints are public: the instruction-tuned model in BF16 (16 shards, about 130GB), an NVFP4 build, and a BF16 base model — all under Apache 2.0, which allows commercial use, modification and redistribution with no separate agreement and no revenue threshold. That licence is the cleanest we have seen on a frontier-class release this autumn.
The headline claim, reported as Ricursive's own and not independently reproduced: 80.52 on Terminal-Bench 2.1, the terminal-agent benchmark, ahead of Reflection Beam 501B (80.1), Meta Muse Spark Open 816B (76.4), Thinking Machines Inkling 975B (63.8) and NVIDIA Nemotron 3 Ultra 550B (56.4) in Ricursive's comparison table. The caveats are in the card itself: the figures mix official model-card scores with Ricursive's in-house runs, scores moved when re-run under the official Terminus 2 harness, and the Preview has had, in Ricursive's words, relatively light post-training. Treat the ranking as a claim to test on your own tasks, not a settled result.
Why renters should care — the size: this is frontier-claimed capability in a 65B envelope, not a cluster job. The BF16 weights are about 130GB, so two 80GB cards or one 141GB H200 hold them; the NVFP4 checkpoint is the single-card route — Ricursive says the model fits on consumer hardware such as the NVIDIA DGX Spark, and its own serving note reports 250 tokens per second on 2×B200 at batch 8 before quantization or custom kernels. At the RunPod Secure rates we read on Nov 5, 2026, that is one H200 at $5.29 an hour for the full BF16 model, or one 96GB RTX PRO 6000 at $2.49 an hour for the NVFP4 build — against the 8-GPU Blackwell nodes this week's 2.8-trillion-parameter release points at.
The backstory, from Ricursive's launch blog: a general-purpose variant of the proprietary model that powers the company's AI chip-design platform, built by a team that grew from one to five people, at a stated full R&D cost of $32 million — which Ricursive calls one-tenth the cost of the previous open-weight agentic-coding leader. The hosted routes at launch are Together AI, GMI Cloud and OpenRouter, with Fireworks announced as following; the weights themselves are a free, ungated download on Hugging Face.
What it means if you rent GPUs
Most of this autumn's open-weight headlines have been trillion-parameter releases that only the scarcest rental tier can serve. Ripple-65B Preview runs the other way: a dense 65B model, a licence with no strings, and a checkpoint sized for one GPU. If its coding scores hold up under independent testing, the cheapest verified cards on our board just became a credible way to run a frontier-class coding agent — and if they do not, the licence and the size still make it the easiest big release of the season to test for yourself.