NEWS → · Hardware · SK hynix
SK hynix demos MARS at SC26: a rack-scale memory pool built for KV cache
Nov 21, 2026
SK hynix used SC26 in Chicago (Nov 15–20) to demonstrate MARS, its Memory-centric AI Rack System: a rack-level pool of CXL memory — DRAM and SSD tiers — that servers and GPUs share for KV cache, instead of every GPU carrying its own copy. The photograph is SK hynix's own, from its Newsroom report of Nov 20, 2026, and shows the MARS exhibit on the show floor. MARS is a demonstration, not a product on sale: SK hynix published no price, no availability date and no measured uplift figure in its report.
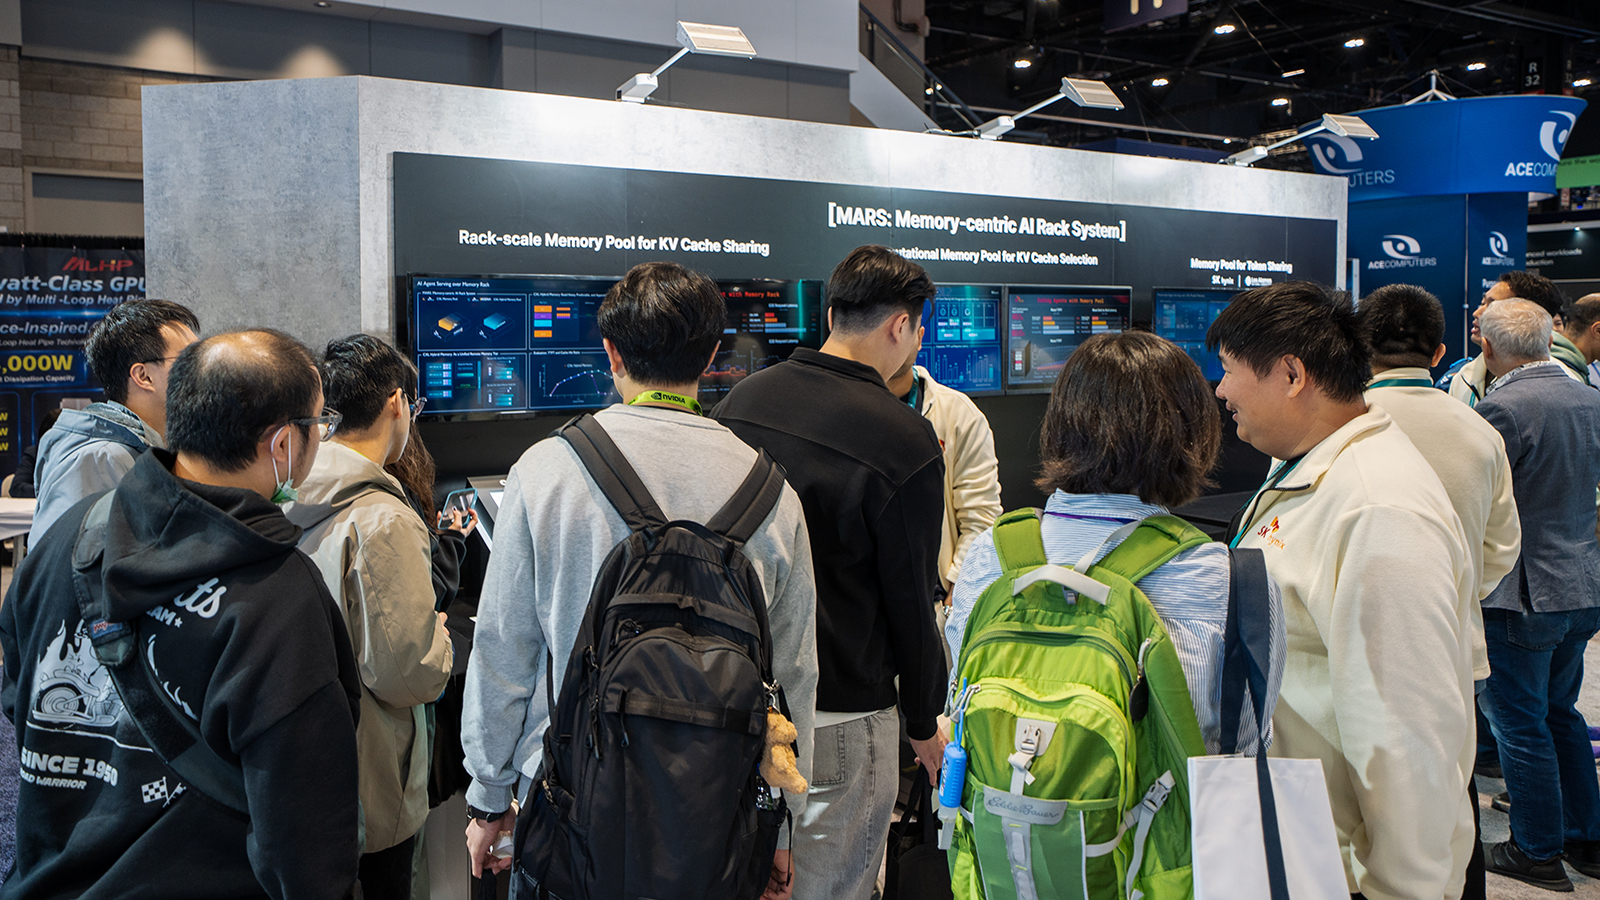
Image: SK hynix via news.skhynix.com
What was shown, from SK hynix's own report: three MARS demonstrations — pooled CXL memory and CXL hybrid memory (DRAM plus SSD) sharing KV cache at rack level; AI-agent serving running over a computational memory pool that connects multiple servers and GPUs; and a multimodal demo sharing CPU-generated tokens through the same pool. Alongside MARS, SK hynix showed KV Cache Offloading over CXL, which it says it verified with SK Telecom in a real LLM inference environment, plus Compute-using-DRAM and its Custom HBM Array work. The report is a booth report from a conference of about 10,000 visitors and 500 exhibitors — evidence of direction, not of a shipping system.
The problem MARS aims at is real and priced daily on our board. In long-context and agentic inference serving, the binding constraint is increasingly KV-cache memory, not raw compute: context windows of a million tokens multiply the cache every concurrent session needs, and today that cache lives in GPU HBM — the most expensive memory in the rack. A shared CXL pool would let a rack hold far more cache in cheaper DRAM and SSD tiers and share it across servers, which is why the HBM market leader showing this design matters even at demo stage.
What it means if you rent GPUs
For GPU renters the honest position is: nothing here can be rented yet, and SK hynix has attached no numbers to it. What MARS signals is where the memory industry expects inference economics to move — cache capacity pooled at rack scale rather than bought GPU by GPU. If pooled-memory serving reaches products, the maths of long-context serving changes: fewer, cheaper GPUs could hold the same concurrent sessions. Until a provider lists it with a price, it stays a direction to watch, and this desk will treat any future quantified claim as the maker's own until independently measured.