NEWS → · Models · Tencent
Tencent releases the Hy4 weights: a 770B flagship you can download — under a licence with a $50M trigger
Nov 20, 2026
Tencent published the full Hy4 weights today, Nov 20, 2026 — the instruct model, an FP8 build and the pre-trained base, on Hugging Face, ModelScope and GitCode, a fortnight after the model reached Tencent's API. The model card, read first-hand by this desk, totals 770 billion parameters with 49 billion active per token, across 78 layers with 256 routed experts of which eight fire, a native vision encoder, a built-in speculative-decoding drafter, and a context window of 1,048,576 tokens. The picture is Tencent's own benchmark chart from the model card. The release does not ship under the plain Apache 2.0 of Tencent's earlier Hy models: it uses the Tencent Hy License, whose section 10 requires a separate written licence from model-as-a-service operators above US$50 million in revenue or 100 million monthly users.
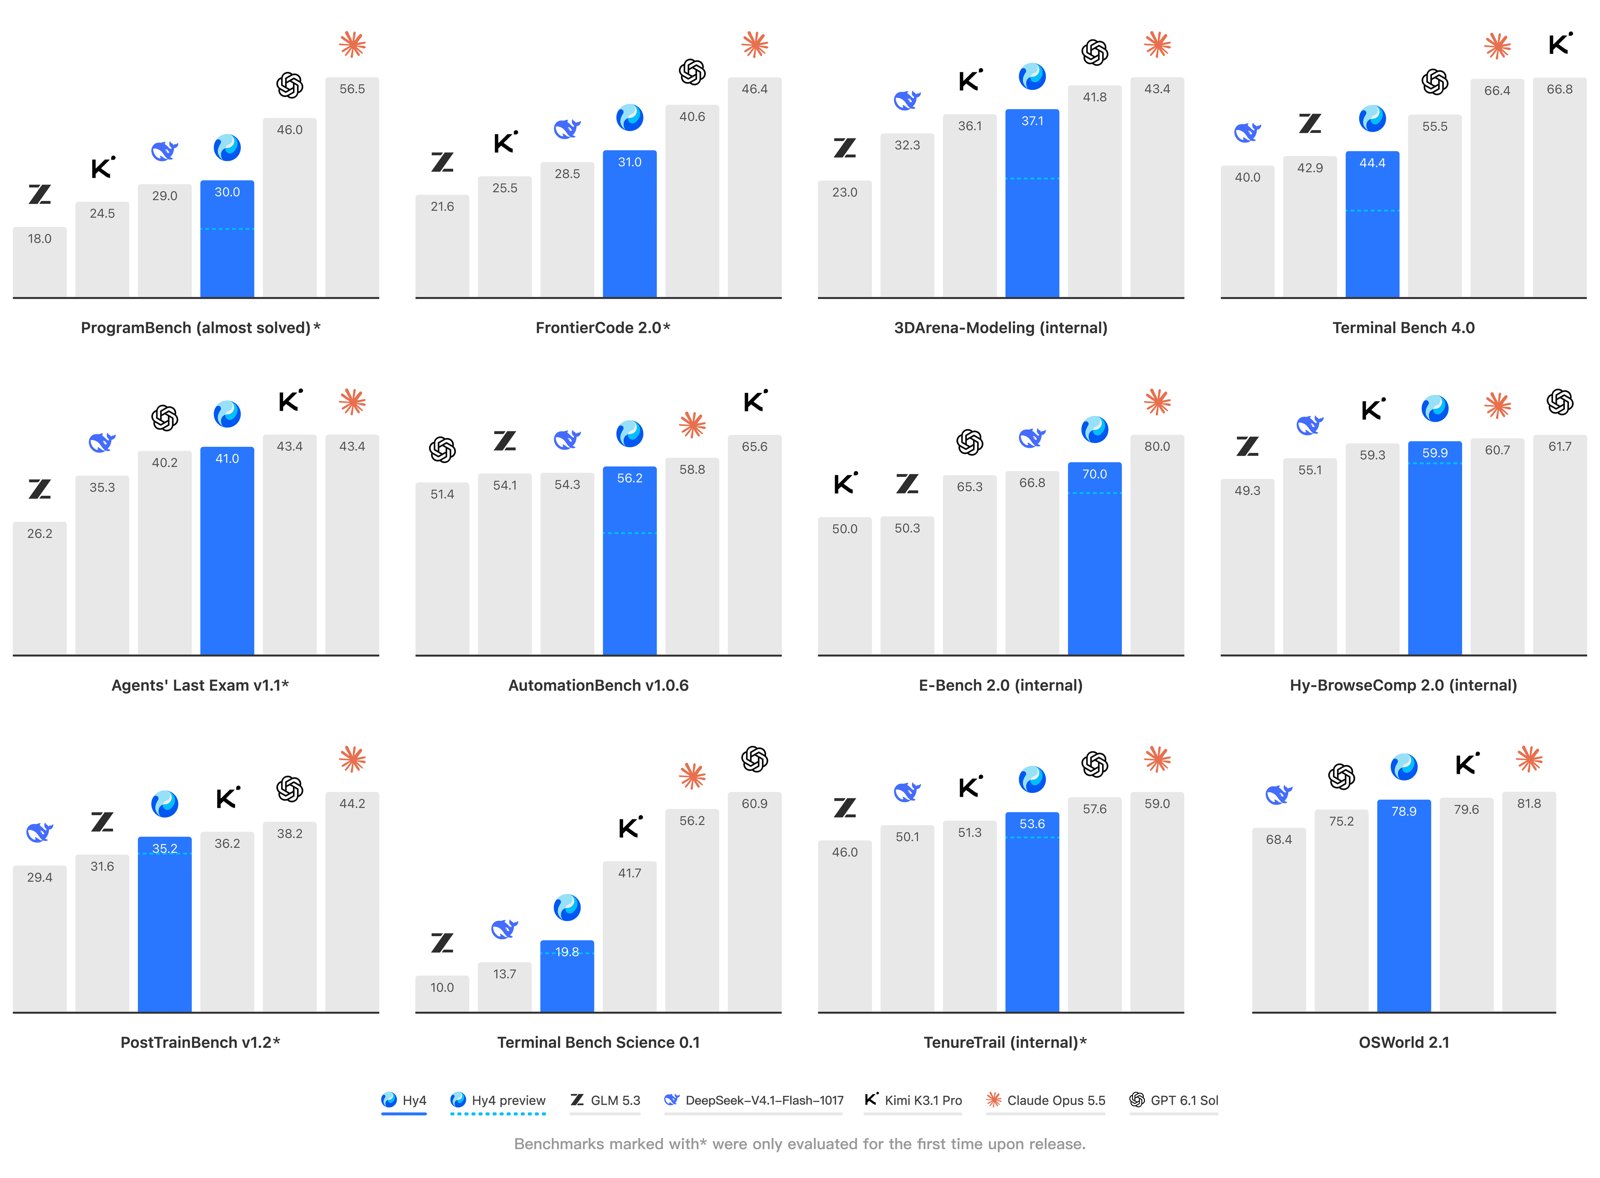
Image: Tencent via huggingface.co
What is in the repositories, from the card itself: Hy4 at about 1.55 terabytes, Hy4-FP8 at about 0.79 terabytes, and the Hy4 base at about 1.54 terabytes, plus a system card. The 770B backbone figure excludes a 1.23B vision encoder and the 3.3B DFly2 drafter, which reuses the model's own KV cache so speculative decoding adds no separate cache. Serving recipes are published for vLLM and SGLang with tensor parallelism across eight GPUs; Tencent ships a prebuilt vLLM image for the FP8 build. Every benchmark on the card is Tencent's own evaluation — the base model scores 91.6 on MMLU and 73.9 on MMLU-Pro in its tables, ahead of the DeepSeek and house baselines it lists — and the card is candid about the gap that remains to the top proprietary models on research-level maths and long-horizon coding. Treat the numbers as the maker's measurements, not independent results.
The licence is the part a renter has to read before the parameter count. Section 10 of the Tencent Hy License — the same clause that shipped with Hy4 flash on Nov 17 — means an operator selling Hy4 inference as a service needs Tencent's separate written licence once its worldwide gross revenue passes US$50 million in any twelve months or its product passes 100 million monthly active users. Purely internal use is exempt. Below those lines the licence is Apache-derived and the weights are free to download and run.
What it means if you rent GPUs
For GPU renters this is a node-scale decision, not a single-card one. By memory arithmetic from the card's own figures, the FP8 checkpoint alone is about 770GB of weights before any KV cache — an eight-GPU node of H200 or B200 class cards is the realistic serving unit, which is exactly the shape of Tencent's own eight-way tensor-parallel recipe; at full precision the weights are about 1.54TB and the job becomes multi-node. The model is now in our catalogue with its sizes worked from the card, and the open-versus-closed maths for a model this size turns on the licence line as much as the hourly rate: self-hosting is unrestricted for internal use, while reselling Hy4 inference at scale is a negotiation with Tencent first.